Explore churn drivers
Clean customer records and investigate contract, tenure, service, and billing patterns.
Machine Learning / Classification study
An end-to-end churn prediction study comparing models and class-imbalance strategies to help prioritize customer retention.
The context
Using the IBM sample Telco Customer Churn dataset, this study investigates which customers are more likely to leave and how a retention team might prioritize outreach. It is an analytical case study, with recommendations based on the sample data.
Explore the evidence / Held-out test set
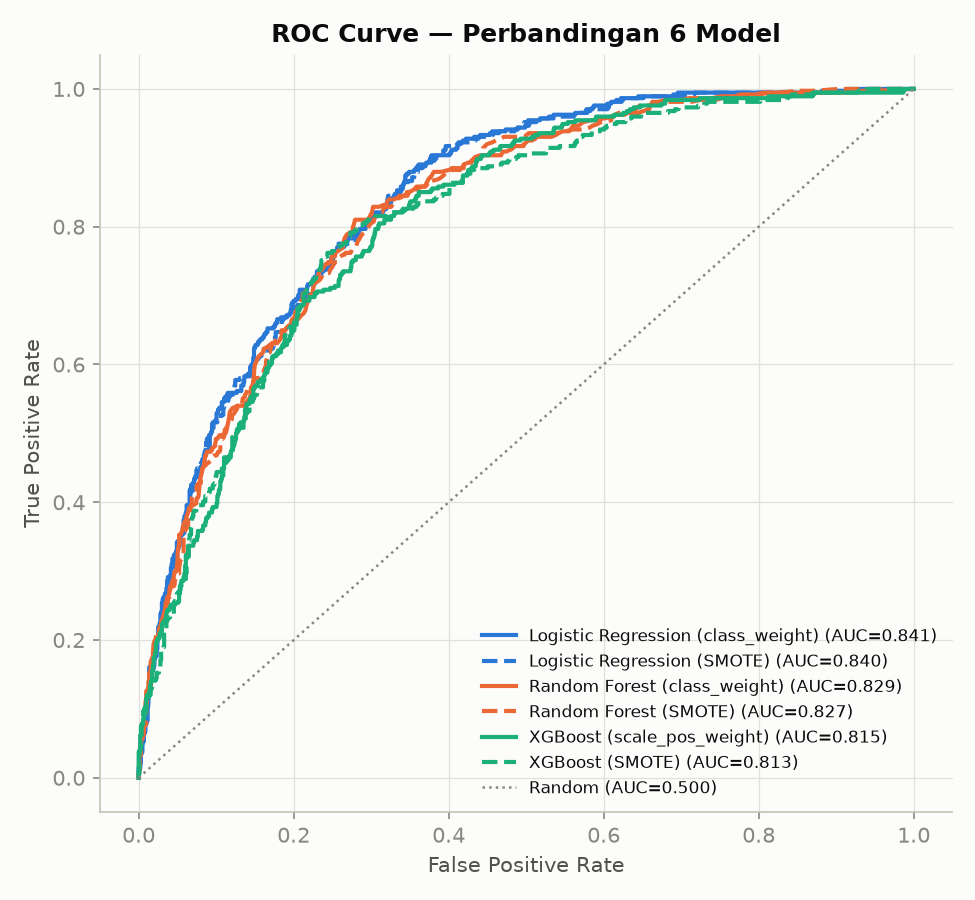
Compare six models and explore the trade-off between finding churners and flagging customers who stay.
ROC-AUC measures ranking across classification thresholds; 0.5 is the random-ranking reference, and 1 is perfect ranking.
Score scale: 0 → 1 · higher is better for the selected metric
Select a bar, or focus it with your keyboard, to inspect all four scores.
| Model / balancing strategy | ROC-AUC | F1 | Precision | Recall |
|---|---|---|---|---|
| Logistic Regression · Class weight | 0.8415 | 0.6162 | 0.5034 | 0.7941 |
| Logistic Regression · SMOTE | 0.8397 | 0.6112 | 0.5000 | 0.7861 |
| Random Forest · Class weight | 0.8286 | 0.5953 | 0.5571 | 0.6390 |
| Random Forest · SMOTE | 0.8268 | 0.5870 | 0.5707 | 0.6043 |
| XGBoost · Positive-class weight | 0.8150 | 0.5810 | 0.5594 | 0.6043 |
| XGBoost · SMOTE | 0.8130 | 0.5722 | 0.5619 | 0.5829 |
Read the trade-off. Weighted Logistic Regression reaches 0.7941 recall at 0.5034 precision: it identifies about 79% of churners, while about half of flagged customers actually churn. The preferred balance depends on the cost of outreach and missed churn.
Scope. These are saved evaluation results from the IBM sample Telco dataset. They are not live predictions or measured business impact. Differences are descriptive; this chart does not establish statistical significance or causality.
Source. View the versioned evaluation CSV ↗ · Download the displayed results
The approach
Clean customer records and investigate contract, tenure, service, and billing patterns.
Evaluate Logistic Regression, Random Forest, and XGBoost with class weighting and fold-safe SMOTE.
Compare held-out ROC curves, recall, precision, and feature importance, then write retention recommendations.
Inside the repository